Hosting AI agents and language models: cloud, hybrid or local?
 Jesse ScherpenJune 4, 20266-minute read
You can run an AI agent or language model in three ways: entirely with a cloud provider, hybrid or fully local. For most small and mid-sized businesses, hybrid is the best choice: your own logic, data and connections sit on your own server, and only the thinking goes through a language model in the cloud. Fully local is only needed when data really isn't allowed to leave the building.
Once you're past experimenting with ChatGPT and want an AI agent that does work on its own, you run into this question. The answer decides what you pay each month, how safe your data is and how dependent you become on a single vendor. In this article we put the options side by side, with the costs and the pitfalls you only run into once the system is actually running.
What is an AI agent made of?
An AI agent isn't one small program, but four parts built on top of each other. For each part, you decide where it runs:
- The language model: the part that understands text and reasons, like GPT, Claude, Gemini or an open-source model such as Llama or Mistral.
- The control layer: the logic that decides which steps the agent takes and in what order.
- The memory: a database with context, earlier conversations and company knowledge.
- The connections: the links to your own systems, so the agent can actually do something, like send an email or put a lead in your CRM.
Option 1: everything with a cloud provider
The fastest start. You build your agent in the environment of, say, OpenAI or in a ready-made platform, and pay per use. The language model is billed per token: a piece of a word that you send or get back.
Pros: instant access to the strongest models, no hardware of your own, and scaling up happens by itself.
Cons: your data goes to an outside party, you have little say over price changes and you're stuck with that platform's choices. Fine for prototypes and tasks without sensitive data. Once the agent sits deep in your business processes, it becomes a risk.
Keep the GDPR in mind: choose a European processing location where possible. OpenAI offers business customers data storage in Europe, Microsoft and Amazon offer language models from European data centers, and Mistral gives you a European provider.
Option 2: hybrid, the approach we usually choose
With hybrid hosting, you separate the thinking from the rest. The control layer, the memory and the connections run on a well-secured server in a European data center, for example with an automation platform like n8n or with custom software. Your business rules, data and access keys stay there. Only what's needed for the thinking goes to a language model in the cloud, without personal data where possible.
The big advantage: you stay in control. If a provider changes its prices or terms, you switch the connection to another model in your own environment. You don't have to rebuild your system.
Option 3: fully local
Sometimes data really isn't allowed to leave the building or your own server. Think healthcare, law firms or work under strict confidentiality agreements. Then you run the language model yourself too: an open-source model on your own hardware or a closed-off server. Tools like Ollama and vLLM make that technically feasible.
Pros: maximum control, no data with third parties and no cost per token.
Cons: above all, a language model needs a lot of memory on the graphics card (VRAM). For a model smart enough for serious work, you need powerful, expensive GPUs. Renting a suitable server easily costs hundreds to thousands of euros a month, and maintenance, security and updates are on you. For a company with twenty employees, that's often overkill.
What does it cost?
Costs are often misjudged, in both directions:
- Through an API the costs seem low: often a fraction of a cent per short request. But if you have thousands of documents summarized every day, it adds up fast. Short instructions, reusing earlier answers and the right model for each task then make the difference.
- Hosting it yourself takes an upfront investment or a fixed monthly amount for rented GPUs, no matter how much you use it.
- The server for the control layer and memory is usually the cheapest part. An agent that handles an email now and then runs on a small server. An agent that constantly searches through large volumes of documents needs more.
For most small and mid-sized businesses with 5 to 50 employees, the API route within a hybrid setup is by far the most sensible choice financially.
From test to production: where it goes wrong
A prototype on a laptop works fine with one user. The problems start when ten employees or a hundred customers ask something at the same time.
- Speed: a local model often has to be scaled down to be fast enough (quantization). That costs some quality. An internal assistant can take two seconds to think, a customer conversation can't.
- Delay between parts: put your database in the same data center as the control layer, or every step adds up.
- Volume: map out in advance how many requests come in per day, so the costs don't climb unexpectedly.
Security: keep your agent from going off the rails
A language model does what its input tells it to, even when that input comes from someone with bad intentions. Take these measures:
- Protect yourself against prompt injection: someone can try to give your agent different instructions through a contact form or chat. Keep system instructions and user input strictly separate, and don't let the agent do anything it isn't allowed to.
- Give as few permissions as possible: an agent that reads leads doesn't need to be able to wipe your CRM.
- Store access keys safely: never in the code, always in protected settings on your server.
- Set limits: on how much the agent can spend or send per day.
- Log everything: what went in and what came out? Without a log, you won't know why the agent made something up.
I'd rather build a system that works for you right away than sell you a thick report about what might be possible.
Jesse Scherpen, owner of SharpClicks
Which option fits you?
- Choose the cloud if you want to test quickly and there's no sensitive data involved.
- Choose hybrid if the agent is becoming part of your daily work and you want control over your data and vendors. For most small and mid-sized businesses, this is the starting point.
- Choose local if laws or agreements with your clients truly rule out sending data, and you have the budget for hardware and upkeep.
How we approach this
Getting a language model running is half the work. The value is in what happens around it. An example: a detailed inquiry comes in by email. The system picks up the email, has the language model pull out the essentials, like name, budget and problem, and puts that neatly into your CRM. Your salesperson calls the same day, without retyping anything. You can see how we built this for our own customer contact, with sensitive information on our own server, in our case on CRM processing.
Read which language model to choose for this, and how to check the output, in getting an AI application built.
Conclusion
Where you run an AI agent isn't a technical detail. It decides your costs, your security and your freedom to switch vendors later. Start in the cloud to test, go hybrid once it gets real, and only choose fully local if you have to.
Want to know which setup fits your process? Book an intro call. Read more about what we build under AI automation.
Frequently asked questions
What does hosting an AI agent mean?
Deciding where the parts of your AI agent run: the language model, the control layer, the memory and the connections to your systems. That can be entirely with a cloud provider, hybrid or entirely on your own server.
Can I run a language model locally?
Yes, with an open-source model such as Llama or Mistral and tools like Ollama or vLLM. For a model that's good enough for business work, you do need powerful GPUs with a lot of memory, and the upkeep is on you.
Is an AI agent that uses an API GDPR compliant?
It can be, but it depends on how you set it up. Choose a provider that processes data in Europe, sign a data processing agreement, don't send personal data along when it isn't needed, and keep your own data and logic on your own server.
What does it cost to host an LLM yourself?
A rented server with GPUs powerful enough for a usable model easily costs hundreds to thousands of euros a month, not counting the upkeep. Through an API, you pay per use. For most small and mid-sized businesses, that's cheaper.
What's the best option for a small or mid-sized business?
Usually hybrid: the control layer, memory and connections on your own server in Europe, and the thinking through a language model in the cloud. That way you keep control over your data without the cost of your own hardware.
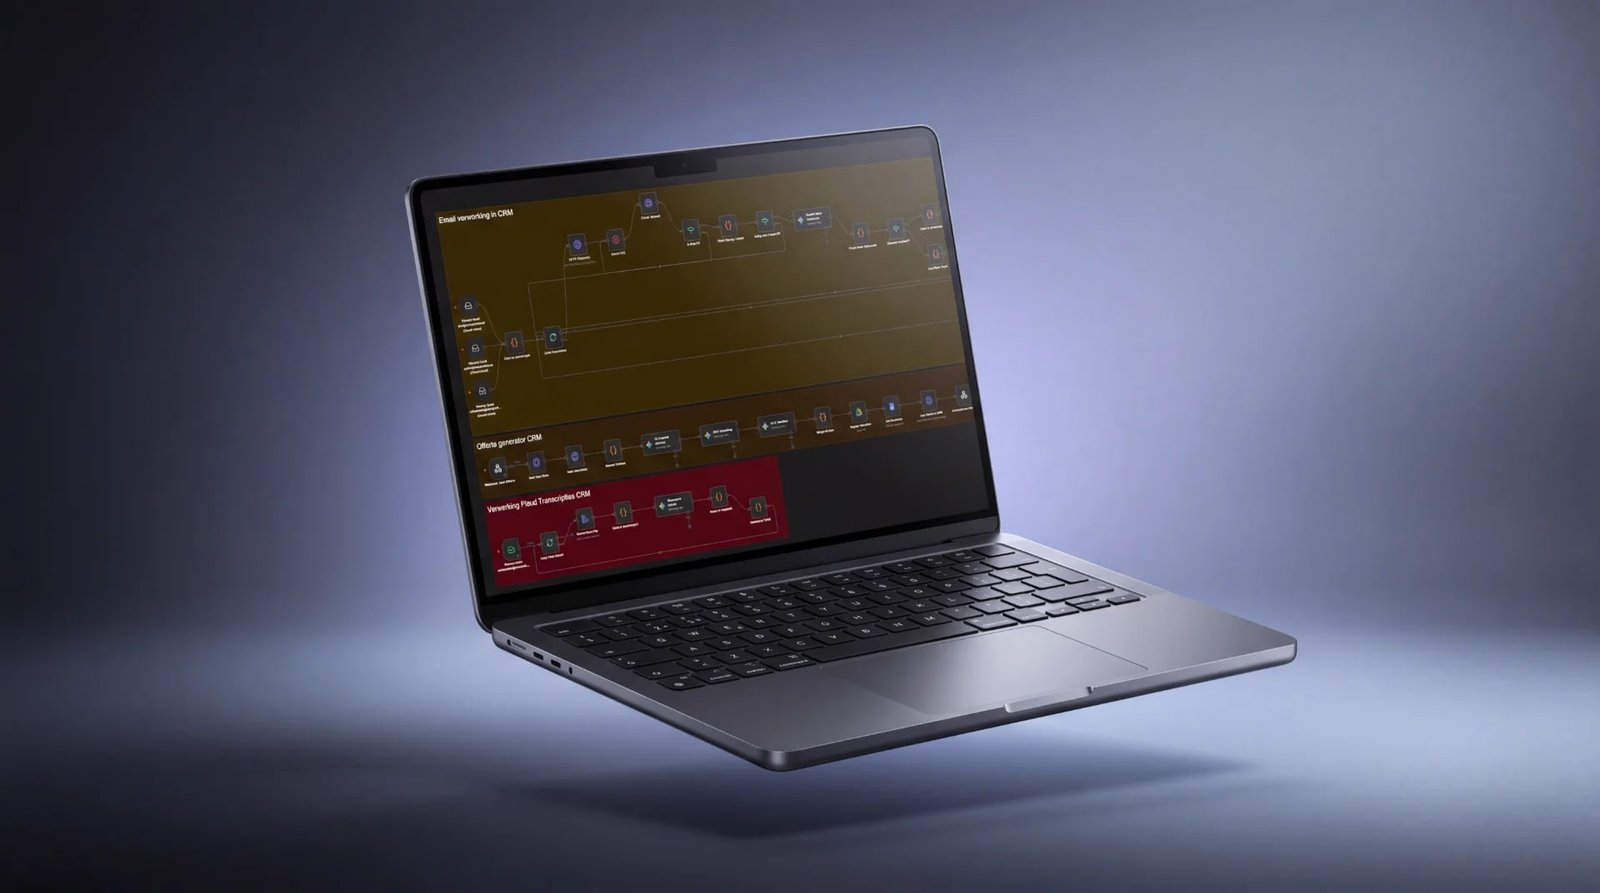 How we built it ourselves
Emails, calls and quotes. Our own system. Sensitive information stays on our own server.
See the case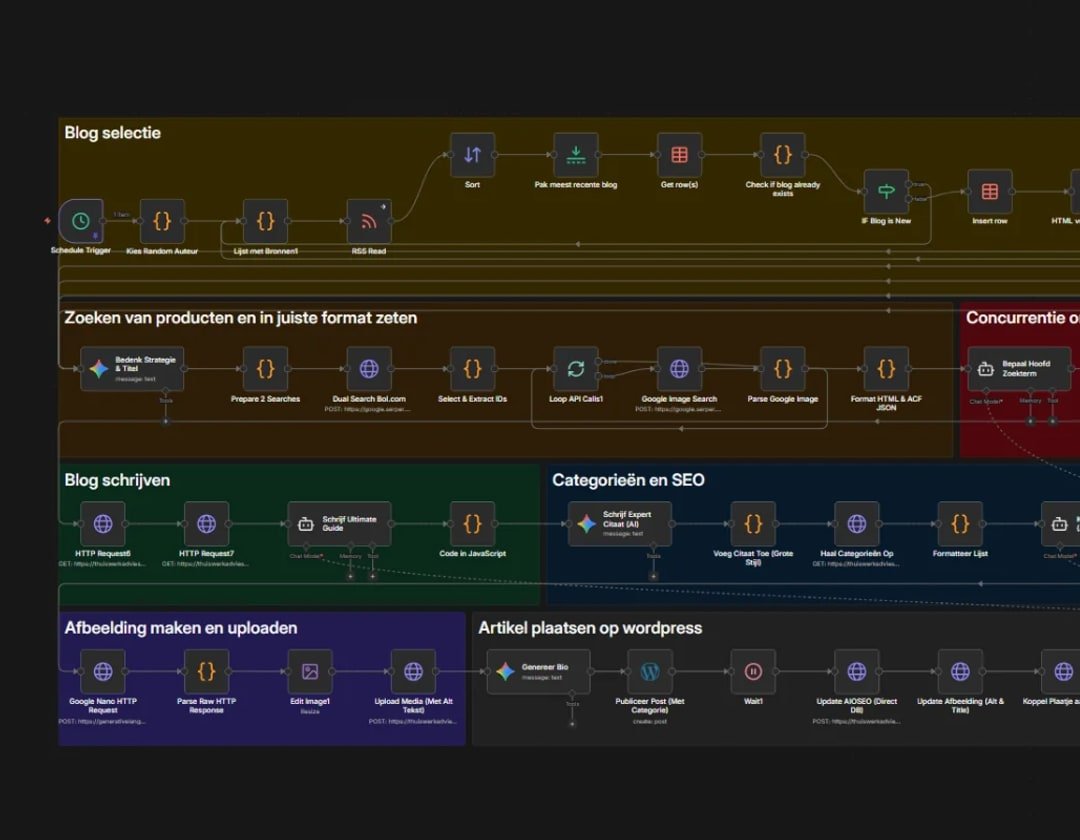 How we can help
AI automation. Work that does itself. One-time build €750 to €2,500.
See the service
Written by Jesse
Jesse Scherpen is the owner of SharpClicks. He studied e-commerce at Windesheim, wrote blogs himself and managed ads for clients, and now builds the systems that take over that work.